
Apple AI Reasoning Study: Does AI Truly Think?
- Simulated reasoning (SR) models, including OpenAI's o1 and claude 3.7 Sonnet Thinking,may rely more on pattern-matching than actual reasoning,according to a recent Apple study.
- The Apple study, titled "The illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity," was conducted by Parshin Shojaee, Iman...
- Researchers evaluated what they termed "large reasoning models" (lrms).
Apple’s latest study throws cold water on the idea that today’s AI truly thinks. Researchers discovered that simulated reasoning (SR) models,including OpenAI’s o1,are vulnerable when tackling novel problems that demand genuine systematic thinking. the study, which tested AI using puzzles like the Tower of Hanoi, reveals a reliance on pattern-matching rather than true reasoning, echoing concerns raised by researchers studying performance on mathematical proofs. These findings suggest that current AI evaluations often overlook the how of problem-solving, focusing solely on the what. News Directory 3 provides deep analysis of tech breakthroughs like this. Could AI’s reasoning limitations be holding back future innovations? Discover what’s next in the ever-evolving AI landscape.
Apple Study: Reasoning AI Models Show Limitations in Complex Tasks
Updated June 12, 2025
Simulated reasoning (SR) models, including OpenAI’s o1 and claude 3.7 Sonnet Thinking,may rely more on pattern-matching than actual reasoning,according to a recent Apple study. the research, released in early June, suggests these models struggle when faced with novel problems requiring systematic thinking. This echoes findings from a United States of America Mathematical Olympiad (USAMO) study in April, which showed similar models achieving low scores on novel mathematical proofs.
The Apple study, titled “The illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity,” was conducted by Parshin Shojaee, Iman Mirzadeh, Keivan Alizadeh, Maxwell Horton, Samy Bengio, and Mehrdad Farajtabar.
Researchers evaluated what they termed “large reasoning models” (lrms). These models attempt to mimic logical reasoning by generating deliberative text, sometimes called “chain-of-thought reasoning,” to aid in problem-solving.
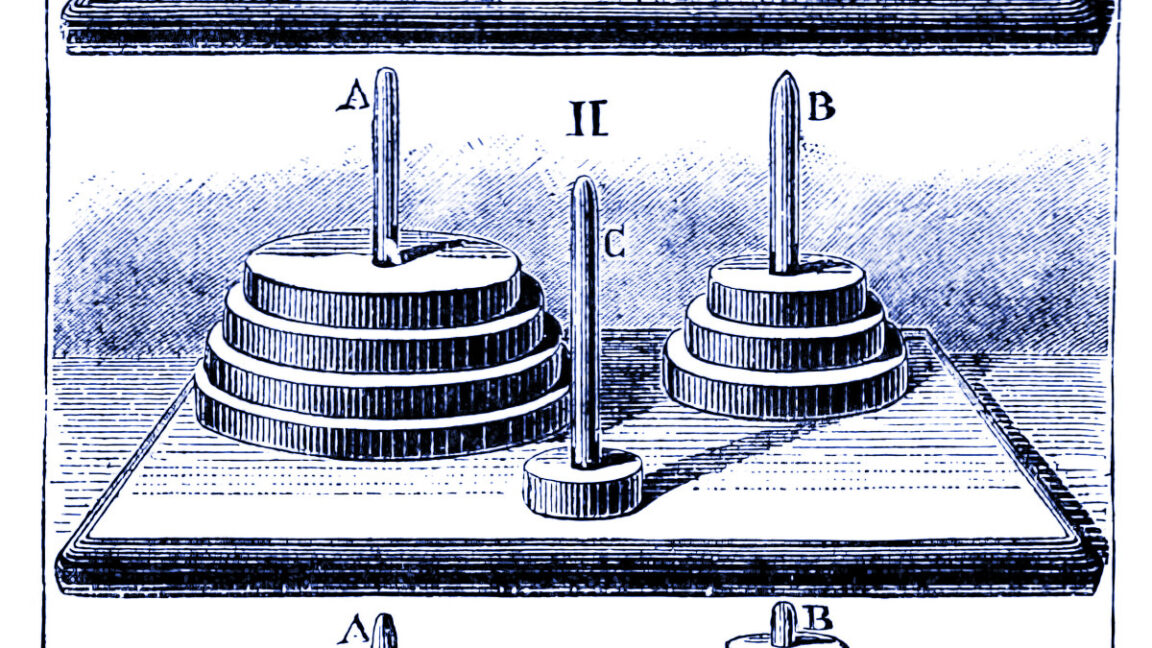
The team tested the AI models using classic puzzles, including Tower of Hanoi, checkers jumping, river crossing, and blocks world. The puzzles ranged in difficulty from simple (one-disk Hanoi) to extremely complex (20-disk Hanoi, requiring over a million moves) to assess the AI’s ability to handle varying levels of complexity.

Figure 1 from Apple’s “The Illusion of Thinking” research paper. credit: Apple
The Apple researchers noted that current AI evaluations frequently enough focus on whether the model arrives at the correct answer, without assessing if the model genuinely reasoned its way to the solution. This means that current tests may not differentiate between true reasoning and simple pattern-matching from training data.
The study’s findings align with previous research, indicating that these models frequently enough perform poorly on novel mathematical proofs. In the earlier study, models achieved scores under 5 percent, with only one model reaching 25 percent, and no perfect proofs among nearly 200 attempts. Both studies highlight a significant decline in performance when models face problems demanding extensive systematic reasoning.
What’s next
Future research may focus on developing new evaluation methods that can better assess the true reasoning capabilities of AI models, moving beyond simple accuracy metrics to examine the problem-solving process itself.