
Code Sharing Practices in Healthcare Prediction Model Studies: A Scoping Review
- Researchers conducting a scoping review of multivariable prediction model studies in healthcare found that code sharing remains inconsistent, nature.com reported.
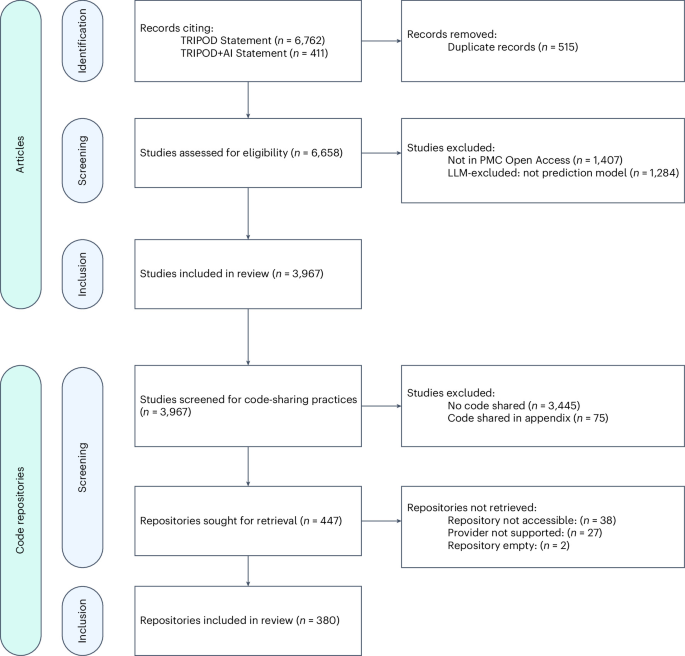
- To examine these practices, investigators analyzed a cohort comprising all PubMed-indexed articles that cited the TRIPOD or TRIPOD+AI statements as of 11 August 2025.
- The investigation restricted its inclusion criteria to primary research articles that developed, validated, or updated a multivariable prediction model using statistical or machine-learning methods.
Researchers conducting a scoping review of multivariable prediction model studies in healthcare found that code sharing remains inconsistent, nature.com reported. While the investigation focused on a defined subset of research that explicitly acknowledges reporting standards, the overall visibility and structure of analytical code across these publications required systematic evaluation.
To examine these practices, investigators analyzed a cohort comprising all PubMed-indexed articles that cited the TRIPOD or TRIPOD+AI statements as of 11 August 2025. This sampling frame targeted studies attentive to reporting guidance, serving as a conservative estimate for code sharing habits. The review addressed two main questions: the proportion of these studies reporting on the availability of analytical code, and the structural and documentation characteristics of the code among studies that did provide accessible repositories.
Scoping Review Evaluates TRIPOD-Citing Studies
The investigation restricted its inclusion criteria to primary research articles that developed, validated, or updated a multivariable prediction model using statistical or machine-learning methods. To enable reproducibility without subscription barriers, the team limited the pool to articles retrievable through the PubMed Central Open Access API. Because of simultaneous publication across different journals, the TRIPOD and TRIPOD+AI statements maintained multiple entries in PubMed, which investigators downloaded, aggregated programmatically, and cleared of duplicate records.

Automated Pipeline and Validation Methods
Data analysis relied on an LLM-assisted pipeline implemented using a predefined structured output schema to handle article-level screening, metadata extraction, and the characterization of associated code repositories. The prompts were refined iteratively on a small set of articles before being fixed for full-cohort analysis. To evaluate the automated pipeline, two independent reviewers manually annotated 500 randomly selected articles.