
NVIDIA Blackwell: MLPerf Training Performance
- NVIDIA's Blackwell architecture has demonstrated leading performance in the latest MLPerf Training benchmarks, particularly excelling in large language model (LLM) training.The NVIDIA AI platform achieved top results across...
- The company is collaborating with various organizations to develop AI factories, accelerating the deployment of next-generation AI applications.
- Submissions at scale utilized two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems.
NVIDIA’s Blackwell architecture dominates the latest MLPerf AI training benchmarks, achieving top results across various challenging tests, including the crucial Llama 3.1 405B pretraining. This success underscores Blackwell’s prowess in accelerating the progress of large language models and its pivotal role in advancing
NVIDIA Blackwell Achieves Top Results in MLPerf AI Training Benchmarks
Updated June 04, 2025
NVIDIA’s Blackwell architecture has demonstrated leading performance in the latest MLPerf Training benchmarks, particularly excelling in large language model (LLM) training.The NVIDIA AI platform achieved top results across all benchmarks, including the demanding Llama 3.1 405B pretraining test.
The company is collaborating with various organizations to develop AI factories, accelerating the deployment of next-generation AI applications. The mlperf benchmarks, now in their 12th iteration, highlight NVIDIA’s platform’s versatility across diverse AI workloads, such as proposal systems, multimodal LLMs, object detection, and graph neural networks.
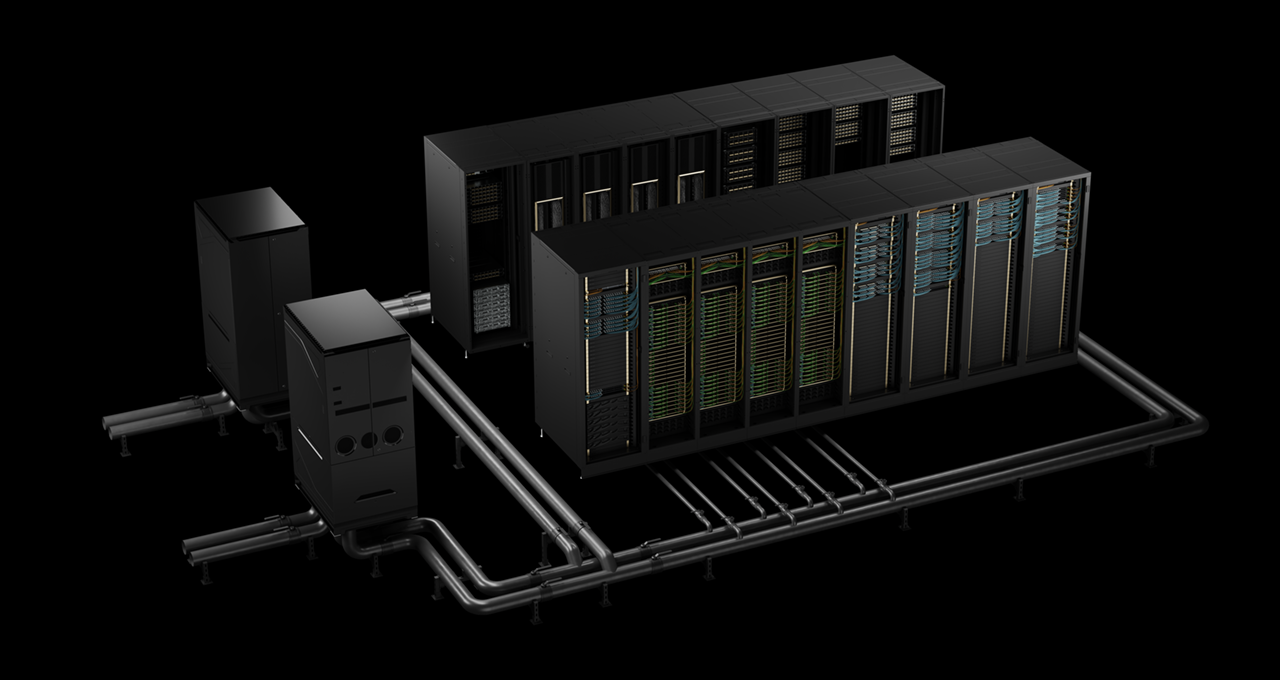
Submissions at scale utilized two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems. NVIDIA also partnered with CoreWeave and IBM, employing 2,496 Blackwell GPUs and 1,248 NVIDIA Grace CPUs to submit GB200 NVL72 results.
Blackwell delivered 2.2x greater performance on the new Llama 3.1 405B pretraining benchmark compared to the previous generation architecture at the same scale. NVIDIA DGX B200 systems, equipped with eight Blackwell GPUs, showed a 2.5x performance increase on the Llama 2 70B LoRA fine-tuning benchmark compared to prior submissions using the same number of GPUs.
These performance gains are attributed to advancements in the Blackwell architecture, including high-density liquid-cooled racks, 13.4TB of coherent memory per rack, fifth-generation NVIDIA NVLink and NVIDIA NVLink Switch interconnect technologies, and NVIDIA Quantum-2 InfiniBand networking. Innovations in the NVIDIA NeMo Framework software stack are also crucial for next-generation multimodal LLM training.
What’s next
These advancements pave the way for agentic AI-powered applications within AI factories, driving innovation across industries and academic fields. The NVIDIA data center platform, encompassing GPUs, CPUs, high-speed fabrics, networking, and software like NVIDIA CUDA-X libraries and NVIDIA TensorRT-LLM, enables organizations to expedite model training and deployment.