
Google Cloud and NVIDIA Announce New Infrastructure for Agentic AI and Sovereign Cloud at GTC Berlin
- Google Cloud and Nvidia announced new AI infrastructure designed for agentic workloads and large GPU clusters during GTC Berlin, ComputerBase reported.
- Google Cloud is expanding its AI Hypercomputer by introducing instances built on Nvidia's Vera-Rubin platform.
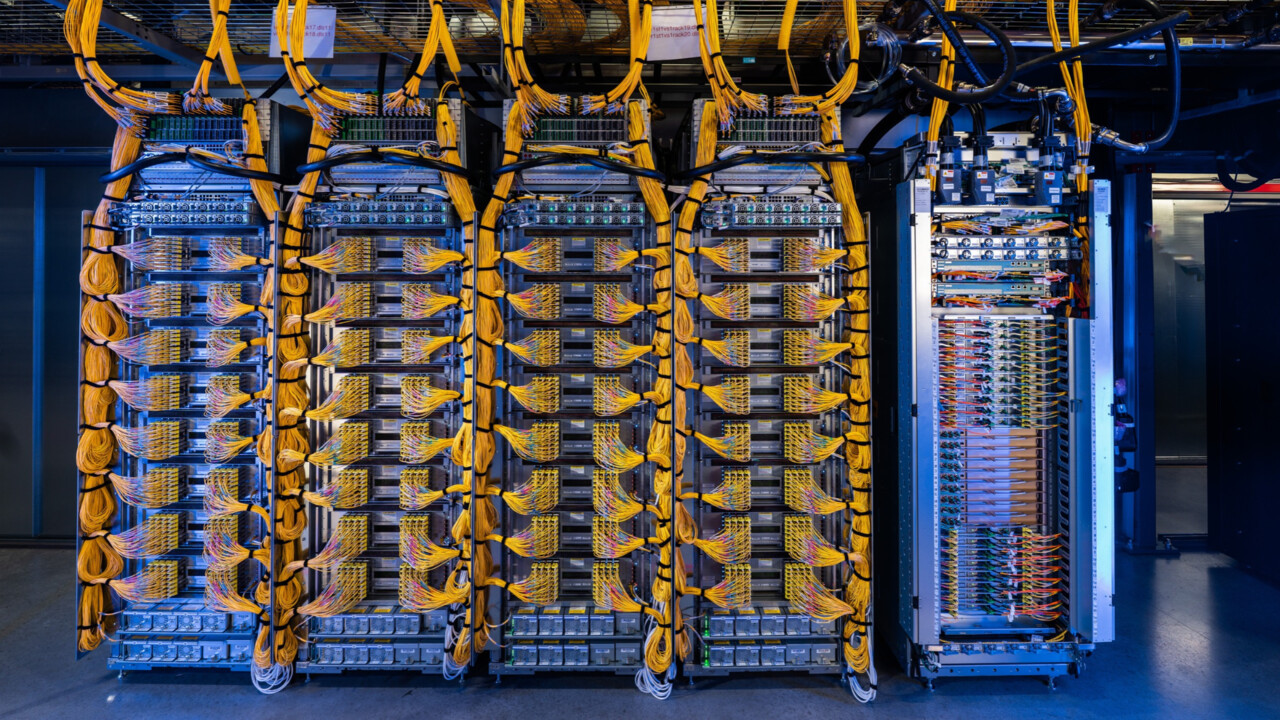
- To support massive computing requirements across multiple buildings, Google introduced the Virgo Network.
Google Cloud and Nvidia announced new AI infrastructure designed for agentic workloads and large GPU clusters during GTC Berlin, ComputerBase reported. The announcements span public cloud enhancements, sovereign local hardware, and confidential computing measures built to help enterprises scale artificial intelligence while maintaining data control.
Vera-Rubin Systems and Virgo Network Scale GPU Clusters
Google Cloud is expanding its AI Hypercomputer by introducing instances built on Nvidia’s Vera-Rubin platform. ComputerBase reported that the A5X instances will become generally available next month, accompanied by new regional data center locations in the EMEA region to address digital sovereignty requirements.
To support massive computing requirements across multiple buildings, Google introduced the Virgo Network. According to ComputerBase, the architecture delivers non-blocking connections capable of linking up to 80,000 Vera-Rubin GPUs in a single facility or scaling up to 960,000 GPUs across multiple distributed locations.

Storage Integration and Sovereign Cloud Expansion
Google Cloud Managed Lustre on A5X instances will support GPUDirect Storage, enabling training and inference data to flow directly into GPU memory via remote direct memory access connections. Additionally, KV-Caching will store and reuse context information across multiple tiers to cut down on repeated calculations and boost inference speed, Google stated in the ComputerBase report. For the operation of distributed AI workloads, Google combines new A5X instances with Google Kubernetes Engine, utilizing features like Managed DRANET and Kueue for job queueing and scheduling to ease the management of RDMA network resources and location-aware planning.
The company also widened model choices within its Sovereign Cloud portfolio. Enterprises can run open models such as Gemma, Mistral, and Nvidia Nemotron on Nvidia hardware while retaining custody of model weights and runtimes.
Air-Gapped Deployments and Confidential Computing
For isolated environments without internet connectivity, Google Distributed Cloud now includes generally available Nvidia B300 GPUs. Google Cloud Blog noted that these accelerators power local deployments of Gemini 3.5 Flash for multimodal processing of text, audio, video, and images. An out-of-the-box enterprise search tool in preview lets workers query proprietary documents within local security boundaries. Beyond air-gapped on-premises setups, customers can run sovereign AI workloads on Nvidia infrastructure using Google Cloud Data Boundary to enforce regional data residency controls, or use Google Cloud Dedicated for an isolated cloud run by local independent partners such as S3NS in France or Thales.
Public cloud deployments gain hardware-enforced isolation through expanded Confidential Computing offerings. ComputerBase reported that G4 instances with RTX Pro 6000 Blackwell Server Edition are generally available, joining existing A4 instances with Nvidia B200 and Intel TDX. The technology is also slated for A4X-Max instances running GB300 NVL72, supported by hardware-based attestation, encrypted NVLink connections, and protected execution environments to secure prompts and models during training and inference.
Adoption Timeline and Remaining Infrastructure Challenges
While the A5X instances launch next month and B300 chips are available on Google Distributed Cloud, questions remain regarding how quickly enterprises can integrate multi-site fabrics like the Virgo Network into existing data center architectures. ComputerBase noted that much of the technical data was provided under nondisclosure agreements, leaving deployment timelines for the massive 960,000-GPU clusters dependent on broader hardware rollouts.