
OpenAI Launches GPT-6 Astra Ultrafast on NVIDIA Blackwell GPUs
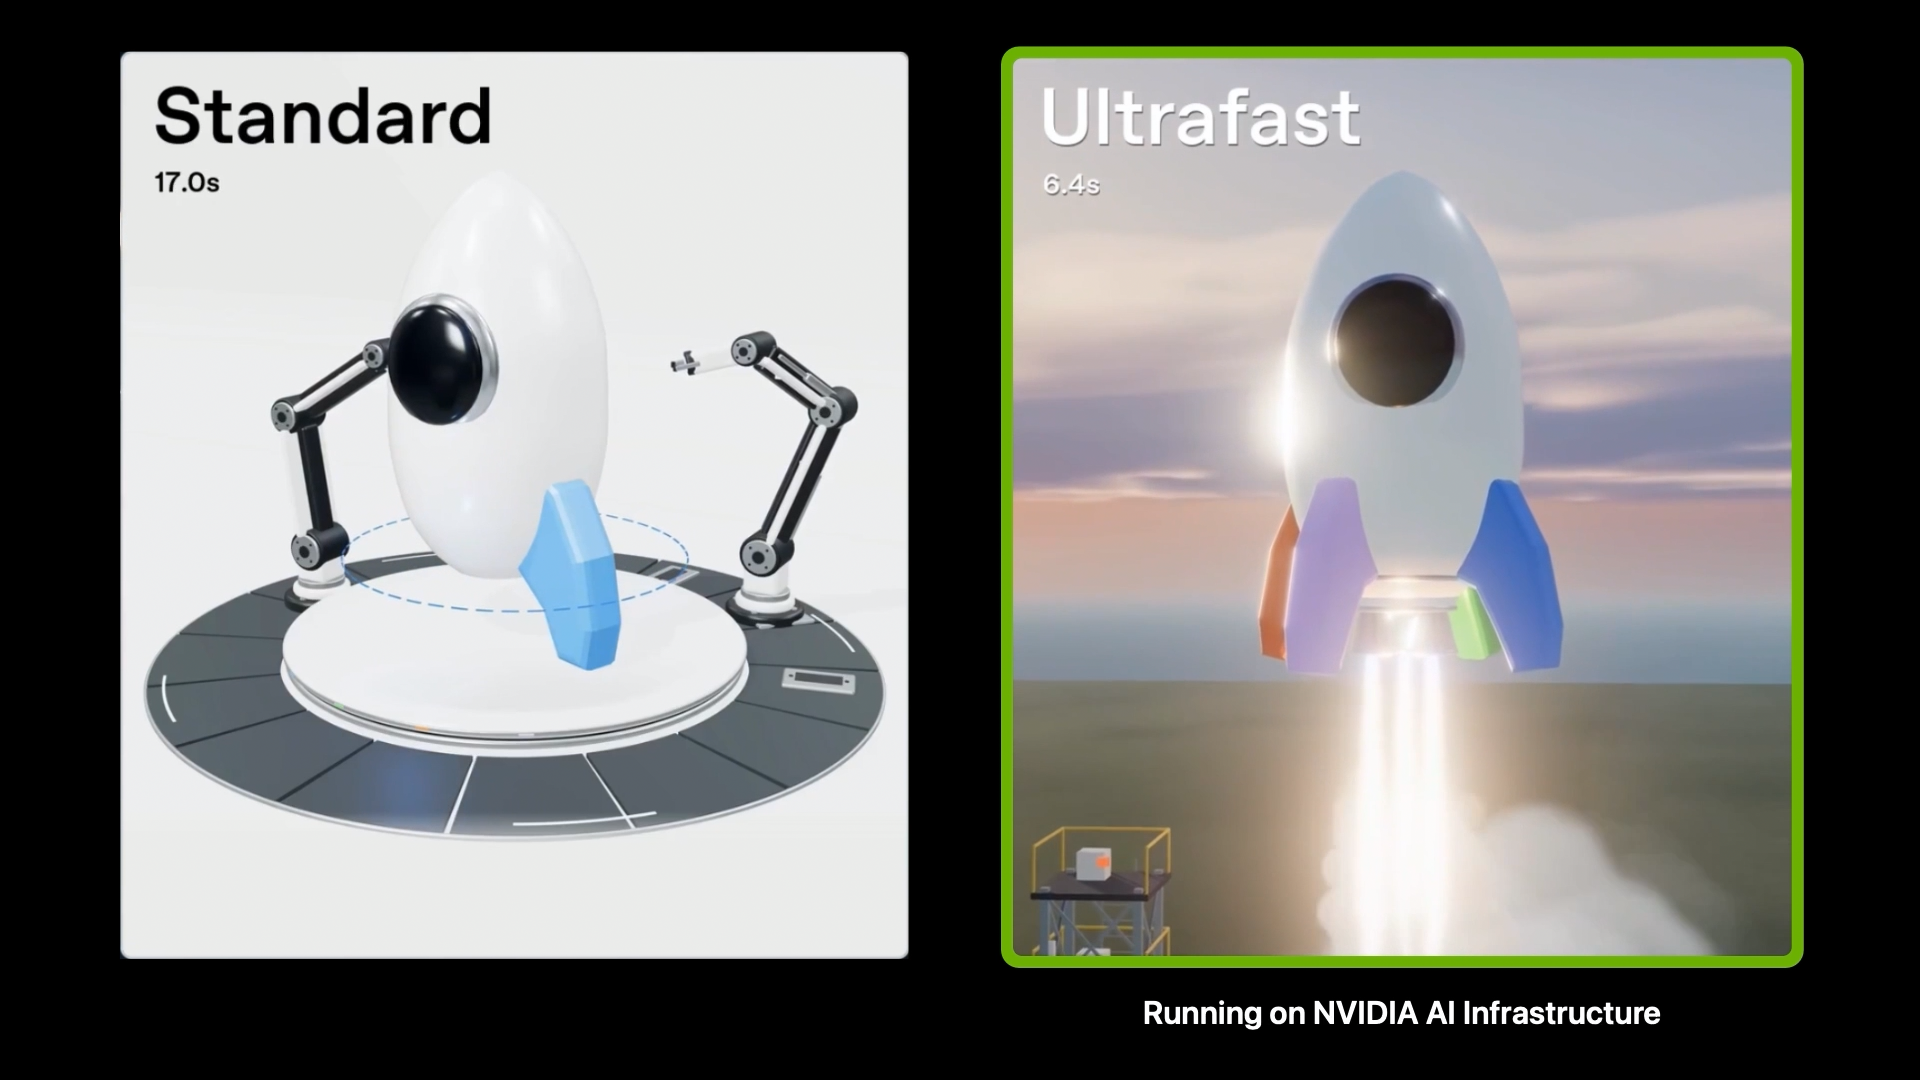
- GPT-6 Astra Ultrafast is available now in the OpenAI API and to eligible ChatGPT Work and Codex users, running on NVIDIA Blackwell GPUs and delivering up to 8x...
- The speed gains come from inference optimizations built into OpenAI's models that tap directly into the capabilities of the NVIDIA Blackwell architecture.
- Astra can turn that knowledge into high-performance kernels that make NVIDIA hardware compelling across the full frontier of latency, throughput and cost.
GPT-6 Astra Ultrafast is available now in the OpenAI API and to eligible ChatGPT Work and Codex users, running on NVIDIA Blackwell GPUs and delivering up to 8x faster token generation than Astra Standard mode. The release aims to shorten coding agents’ edit-test-debug cycles and reduce response times during multi-step developer workflows.
How does NVIDIA Blackwell hardware accelerate GPT-6 Astra Ultrafast?
The speed gains come from inference optimizations built into OpenAI’s models that tap directly into the capabilities of the NVIDIA Blackwell architecture. Philippe Tillet, inference lead at OpenAI, reported that NVIDIA’s deep investment in tooling and documentation enabled the team to make their models exceptionally good at programming Blackwell and Rubin GPUs. Astra can translate that knowledge into high-performance kernels designed to optimize latency, throughput, and cost.
Astra can turn that knowledge into high-performance kernels that make NVIDIA hardware compelling across the full frontier of latency, throughput and cost. With Astra Ultrafast, that means faster model responses as agents write code, use tools and work through complex tasks.
Philippe Tillet, inference lead at OpenAI
Why do faster response times matter for developer workflows?
Developer tasks often rely on repetitive loops where an agent writes code, utilizes a tool, checks the results, and decides on the next step. Cutting down the time spent generating responses between these tool calls makes interactive applications feel significantly more responsive. When these delays multiply across an entire automated workflow, faster generation directly accelerates complex coding and debugging cycles.
How are OpenAI and NVIDIA continuously improving inference performance?
Performance optimization continues even after deployment. OpenAI reported using its own internal models to help refine the inference software running on NVIDIA GPUs. Uday Ruddarraju, chief technology officer of compute at OpenAI, stated that the company used internal models to optimize inference on the hardware, while NVIDIA’s platform programmability helped deliver the acceleration behind the new mode.
Our work with NVIDIA is helping us make AI faster and more useful. We used our internal models to optimize inference on NVIDIA GPUs, and NVIDIA’s programmability helped us deliver the acceleration behind Astra Ultrafast.
Uday Ruddarraju, chief technology officer of compute at OpenAI
This programmable platform allows developers and researchers to reuse the same infrastructure across model training, inference, and reinforcement learning as architectures evolve. That flexibility helps engineering teams repurpose compute resources when demand shifts, improving overall utilization and avoiding the need to overprovision for individual workloads.
Where can developers access GPT-6 Astra Ultrafast today?
Developers can access GPT-6 Astra Ultrafast through the API immediately, alongside eligible ChatGPT Work and Codex users. Implementation details, pricing structures, and access guidelines are available through the official Ultrafast guide.