
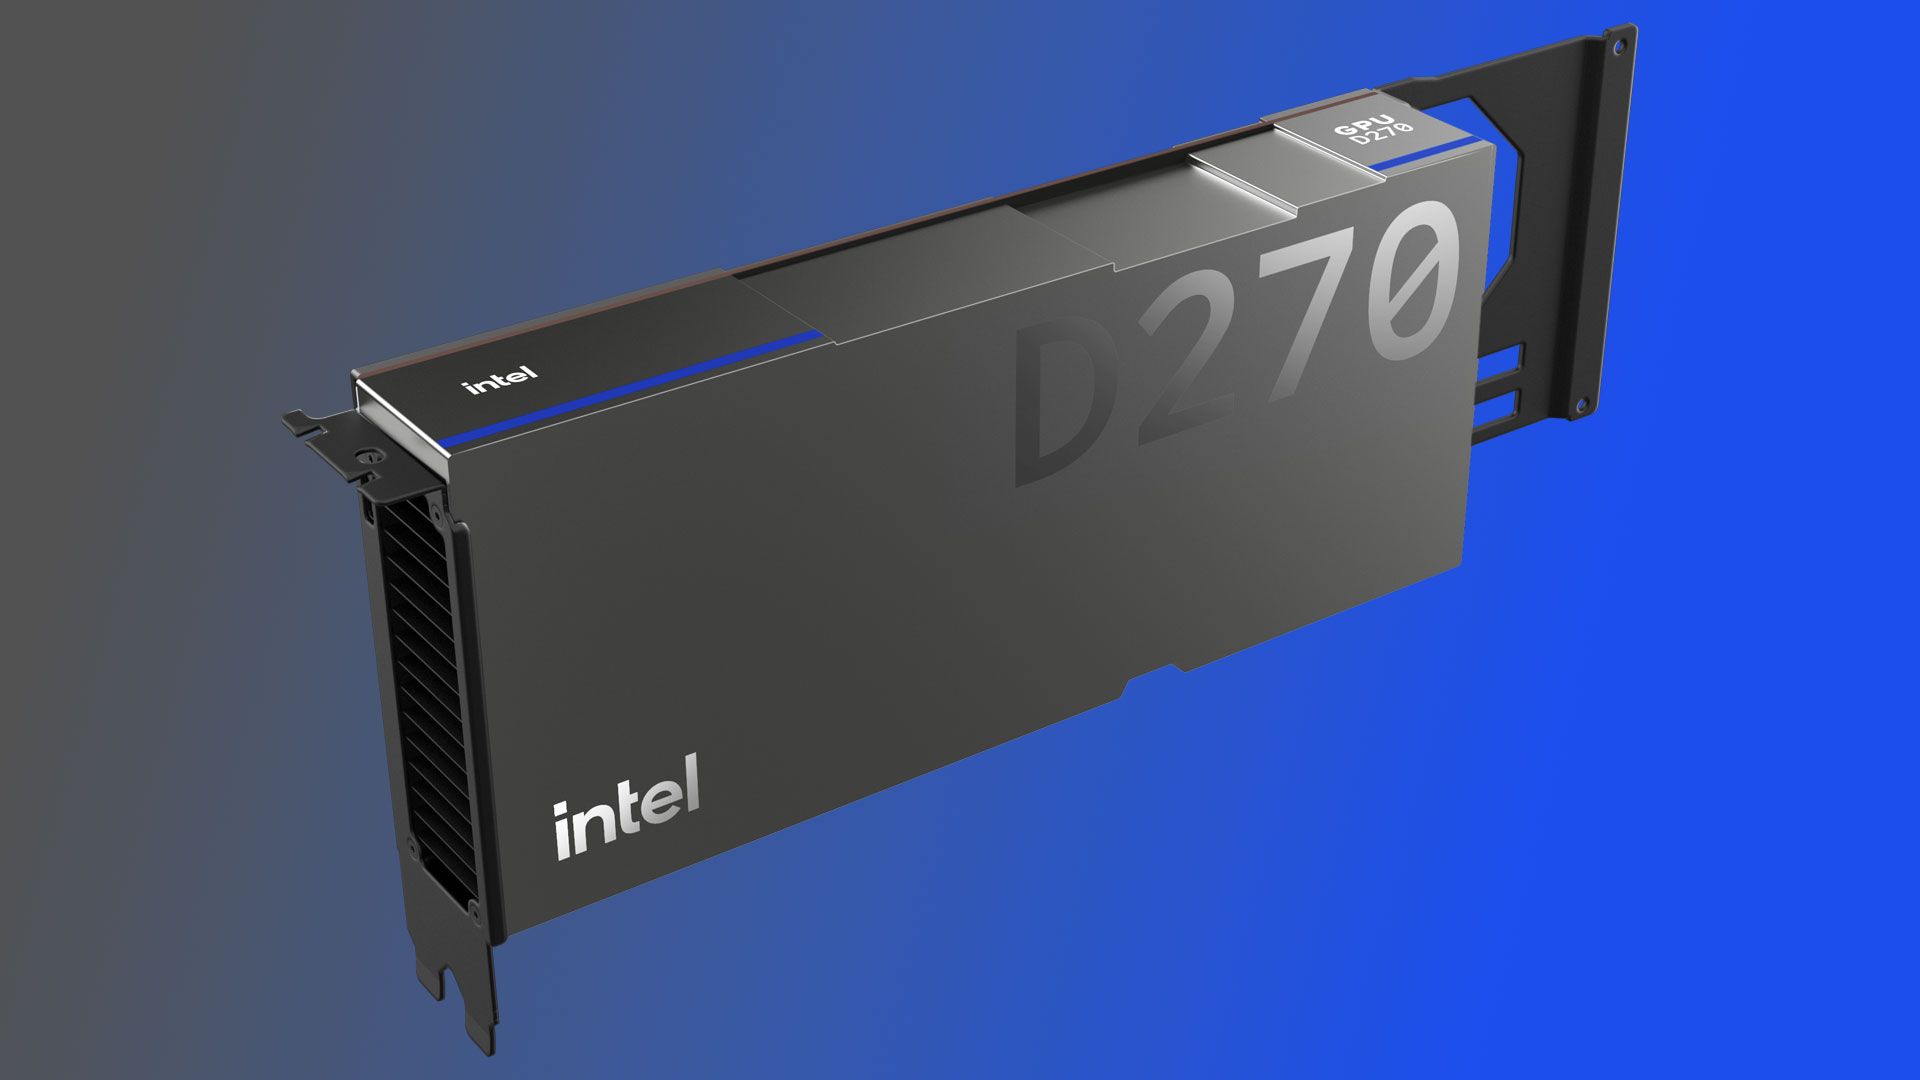
Intel Unveils GPU D-Series AI Accelerators with 1.3 PFLOPS Performance
- Intel has unveiled the formal product family name and performance targets for its upcoming artificial intelligence inference accelerator previously known as Crescent Island, launching the hardware under the...
- According to ServeTheHome, the first accelerator based on the Crescent Island silicon carries the model designation D270.
- The GPU D-Series is manufactured in an air-cooled PCIe form factor with a Total Design Power rating of 350W, according to tomshardware.com.
Intel has unveiled the formal product family name and performance targets for its upcoming artificial intelligence inference accelerator previously known as Crescent Island, launching the hardware under the Intel GPU D-Series banner at the Open Compute Project Global Summit on October 12, 2026.
Intel GPU D-Series Hardware Specifications and Architecture
According to ServeTheHome, the first accelerator based on the Crescent Island silicon carries the model designation D270. The chip utilizes an enhanced version of the company graphics architecture designated as Xe3P, featuring 32 Xe Cores and 256 XMX matrix engines running at a clockspeed of roughly 2.5 GHz. Unlike traditional graphics processors, ServeTheHome reported that the architecture lacks most or all graphics-specific functional units, operating entirely as a massively parallel computing accelerator.
The GPU D-Series is manufactured in an air-cooled PCIe form factor with a Total Design Power rating of 350W, according to tomshardware.com. The hardware supports up to 480GB of LPDDR5X memory through original design manufacturer configurations, while standard Intel variants utilize 160GB. The memory subsystem operates across a 20-chip, 80-channel bus clocked at roughly 9,375 MT/s to deliver the disclosed 1.5 TB/s of bandwidth, as detailed by ServeTheHome.

Performance Benchmarks and Competitive Positioning
The newly announced Intel GPU D-Series occupies a distinctly different performance envelope and infrastructure footprint than flagship liquid-cooled hardware such as Nvidia’s Vera Rubin NVL72 system, where each Rubin GPU reaches 17.5 PFLOPS of FP8 throughput with power demands measured in kilowatts, tomshardware.com reported. Instead, Intel designed the 350W D-Series chips for deployment in traditional air-cooled rack servers scaling up to eight GPUs, similar to Nvidia HGX configurations.
While ServeTheHome noted that Intel’s 1.3 PFLOPs FP8 figure sits below competitors like AMD’s PCIe CEM form factor MI350P accelerator—which offers a theoretical peak of 2.3 PFLOPS of dense FP8 matrix math—the hardware is built to be smaller and more cost-optimized.
Target Workloads and Software Ecosystem Requirements
Intel highlights the suitability of the GPU D-Series for large language models, long-context inference, and concurrent inference services, aiming to establish a foundation for multi-tenant AI services, robotics, and other latency-sensitive workloads, according to Yahoo Tech. To enable distributed inference deployments where multiple GPUs act as a unified system, Intel is relying on the common Xe software foundation built across its Xe Cores in integrated and discrete graphics products.

To bring the accelerators into enterprise data centers, Intel stated that it is collaborating with a broad ecosystem of original equipment manufacturers, original design manufacturers, neoclouds, independent software vendors, appliance providers, and AI-native companies, as reported by Yahoo Tech.
Commercial Availability and Market Outlook
Customer sampling of the GPU D-Series products is currently underway, though Intel has not disclosed a timeline for a broad commercial launch, according to Yahoo Tech. The release follows the discontinuation of earlier data center GPU efforts, including the Ponte Vecchio-based Data Center GPU Max family and its subsequent canceled follow-ons.
Tomshardware.com noted that the processor represents an interim product designed to target the AI inference market with a cost and power-optimized component as agentic workflows and model intelligence demands continue to expand across the computing industry.