
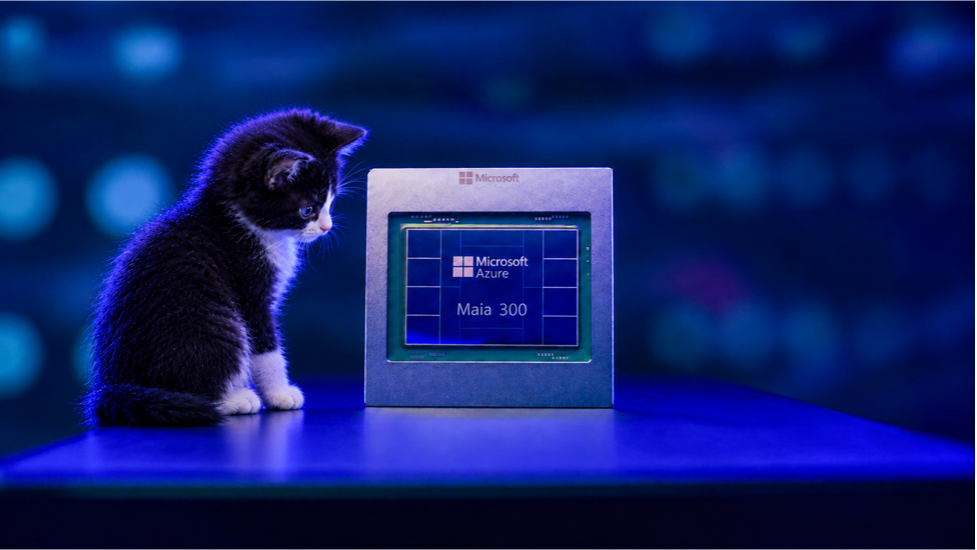
Microsoft details Maia 300 artificial intelligence accelerator
- Microsoft detailed Maia 300, launching its third-generation artificial intelligence inference accelerator designed to run models in products like Copilot.
- Each Maia 300 accelerator carries 288 GB of HBM4 memory operating at 18 TB/s.
- Memory-controller and input-output functions sit on separate dies to optimize bandwidth and connectivity.
Microsoft detailed Maia 300, launching its third-generation artificial intelligence inference accelerator designed to run models in products like Copilot. Jon Peddie Research reported that the new custom silicon targets the decode phase of language model processing, where chips wait on data fetched from memory.
Maia 300 Memory Bandwidth and Rack Capacity
Each Maia 300 accelerator carries 288 GB of HBM4 memory operating at 18 TB/s. That bandwidth figure reaches 2.5 times the capacity of the previous Maia 200 chip. Ninety-six accelerators fill a 167 kW rack, and up to 128 racks link together to form a 12,288-accelerator superpod.
TSMC builds the compute dies on its N2P process. Memory-controller and input-output functions sit on separate dies to optimize bandwidth and connectivity. The silicon moves to a non-uniform memory organization across chiplets, allowing software to place data near the specific compute units using it. Vector-engine instructions target inference kernels like softmax and low-precision data casting, while the chip adds hardware conversion for enhanced MXFP4 and sub-3-bit storage formats.
Liquid Cooling and Single Fabric Networking
Each tray holds four accelerators alongside its own host processor, memory, storage, and cooling infrastructure. Six switch ASICs housed in three liquid-cooled switch trays connect all 96 accelerators in a single rack. Direct links join accelerator pairs inside a tray, while a switched electrical fabric covers the rest of the rack. Optical second-tier switches connect up to 128 racks into a superpod.
A single Ethernet-based fabric handles both scale-up and scale-out traffic without requiring a separate network card. Liquid cooling removes more than 80% of the thermal load, while air cooling manages memory and storage. Operators can connect the system directly to facility water or utilize a heat-exchanger unit for air-cooled data centers.
Microsoft Production Plans and Nvidia Hardware Integration
Production deployments of Maia 300 begin in 2027 as part of a multi-gigawatt rollout. Microsoft schedules GitHub Copilot and Foundry to adopt the hardware by the end of 2026, following Maia 200 deployments for Copilot and the MAI internal model team. The chips run models from OpenAI, Microsoft, and open-source families.
Microsoft continues its commitment to Nvidia hardware through a five-year contract with data center operator IREN, worth about $9.7 billion, to supply computing on Nvidia GB300 systems supporting 200 MW of load. Microsoft accepted the first phase of that Nvidia deployment in August, with the remaining phases scheduled through the fourth quarter of 2026 and grace periods running into early 2027.
Microsoft claims a fully populated Maia 300 rack delivers up to seven times the token throughput of a Maia 200 rack and 40% more tokens per megawatt than leading GPU systems. However, Microsoft has not published matched test conditions, independent validation, or measured dollars-per-token comparisons for the GPU claim.
Unanswered Questions in Azure Infrastructure Scaling
Microsoft has not stated what share of its total artificial intelligence workload Maia will handle, whether measured in requests, computing power, or financial cost. The company also names no outside customers for the custom silicon, leaving open whether external Azure renters will access Maia hardware or remain on Nvidia architectures.